
June 28, 2026 12:12
1 min
Velqor Inc
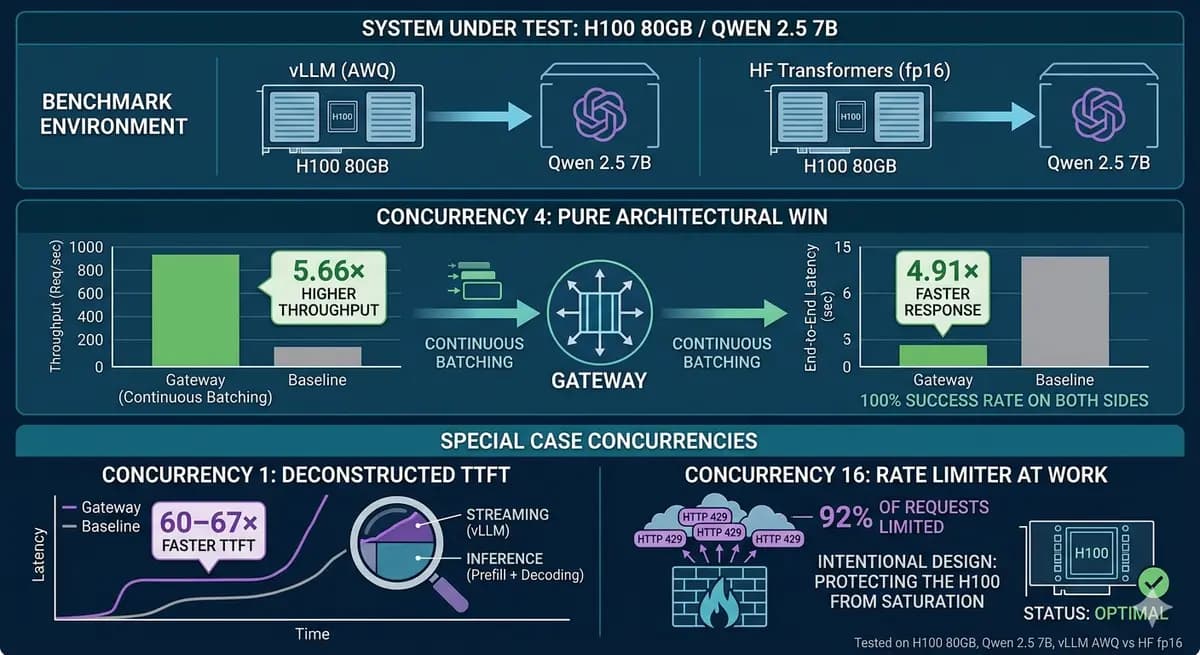
The results are in for the rebuilt LLM gateway, and the performance gains over the naive HuggingFace baseline (using the same Qwen 2.5 7B model) are massive.
Here are the actual benchmark numbers:
- 4.91× faster end-to-end at $c=4$ (with a 100% success rate on both sides)
- 5.66× higher throughput thanks to vLLM continuous batching
- 92% HTTP 429s at $c=16$—proving the rate limiter is working exactly as intended, not failing
- 2 silent bugs caught mid-run (a CPU baseline issue and a SHA mismatch)
Version 0.2.0 is still in progress, but this benchmark pass proves the architecture is solid. Next up: overhead profiling and a deep dive into that "5ms budget."
Full write-up here: https://orhunkupeli.hashnode.dev/the-numbers-benchmarking-my-llm-gateway-on-a-h100
Keywords
What we do in this area
Read next
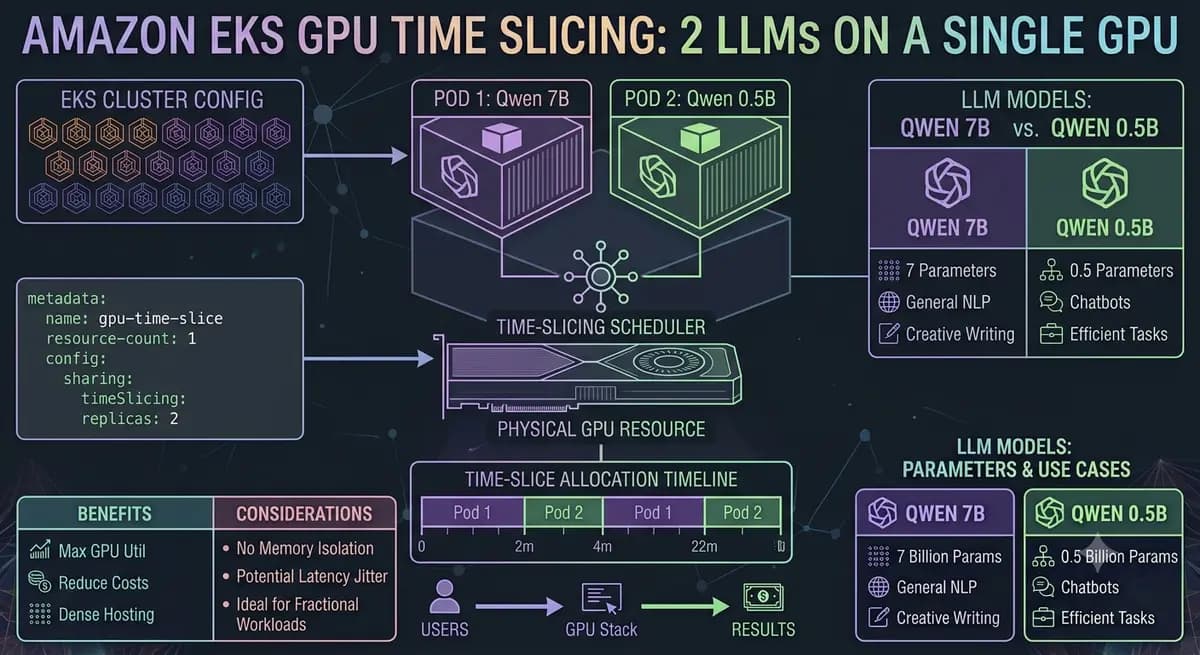
One GPU, Two LLMsWhat I was aiming simple in theory: deploy two open-weight LLMs behind a custom gateway, on Kubernetes, infrastructur...
Maximizing Business Continuity with Redis CacheImplementing Redis cache is vital for continuous service delivery, offering significant infrastructure performance en...
Effective Strategies for Kubernetes Cost OptimizationOptimizing Kubernetes costs is crucial for managing cloud expenses, achievable through strategic tools and approaches.